

See it made
About this use case
A scorecard that names the model your team uses for one recurring job, with a runner-up, the cost and wait of each, and the inputs to rerun it when a new model ships. For team leads and leads of craft. The models and settings in this use case are as of October 2026.
See moreSee less
- A dated scorecard that names your team's model for one recurring job, with a runner-up, cost and wait.
- Change only the model: same prompt, same reference, same aspect ratio, each at its highest quality setting.
- Four runs, one per model, then a second seed for the top two; started in parallel, they finish in the time of the slowest.
Step by step with an agent, through the Scenario MCP (6 steps)Hide the steps
Connect the Scenario MCP
Connect your agent to the Scenario MCP and sign in once at mcp.scenario.com. Then tell it which Scenario team and project to use for the session, so every output lands there.
Give the agent the files
The approved studio image of the car, the reference for every model. Upload it with the agent or give it its asset ID. Use a real brief from your team's work, not a showcase prompt.
Brief the agent
One prompt, one reference, one take per model: only the model changes. The agent can also start from recommend for image to image at quality priority to build the shortlist.
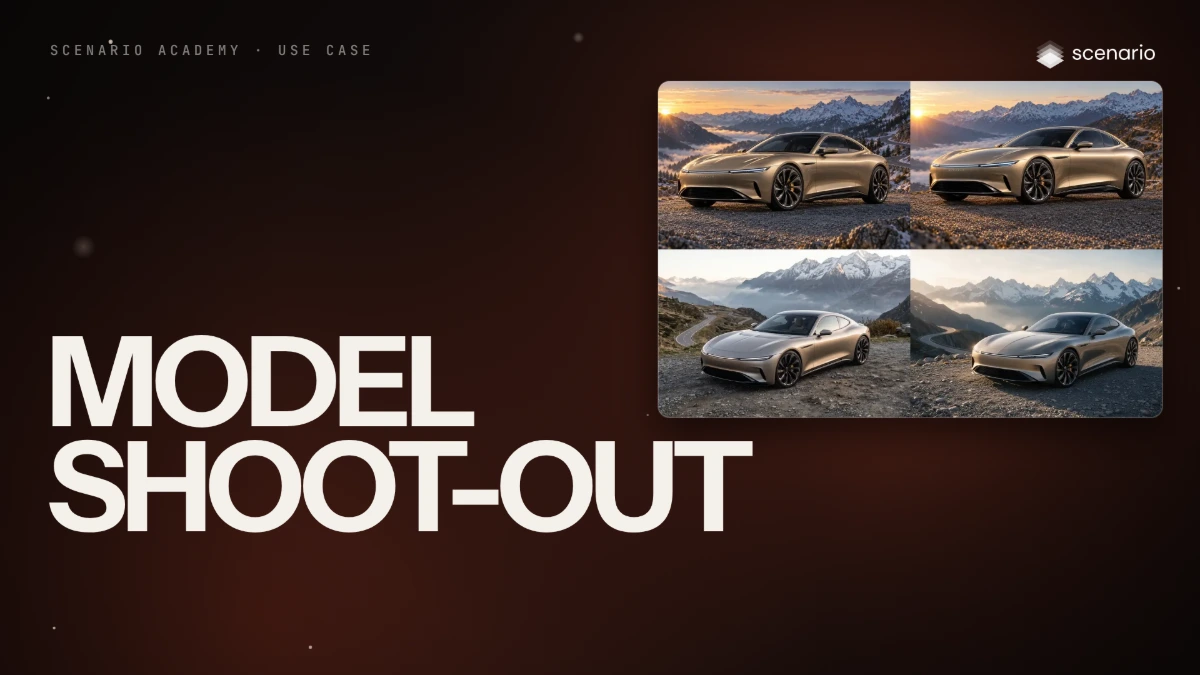
PromptRun a model shoot-out on one brief. Change only the model: the same prompt, word for word, and the same reference for every run. Never rewrite the prompt for a model. Reference: the studio image of the car, passed as referenceImages, an array with its asset ID. Prompt, word for word: The exact car from the reference image, with its body shape and proportions, liquid satin champagne paint, one continuous thin LED light bar across the full width of the nose, the spaced AURELLE wordmark in chrome capitals centered under the light bar, wide dark lower intake with fine horizontal slats, dark twisted multi-spoke turbine wheels with gold brake calipers, and black glass roof unchanged, parked on a gravel overlook on a high mountain pass at sunrise. Snow-capped peaks and a winding road behind, low warm sun from the left raking along the side of the car, cold blue shadows, thin mist in the valley below. Three-quarter front view at headlight height, the light bar lit and the AURELLE wordmark facing the camera and sharp. Soft contact shadow under the tires on the gravel. 3:2 landscape. No other cars, no people, no other text or logos. Style: automotive launch photography, controlled reflections, perfect panel gaps, no other brands. Candidates and settings, one image each, at each model's highest quality: - GPT Image 2.5 Sunburst (model_openai-gpt-image-2-5-sunburst): width 1536, height 1024, quality high - GPT Image 2.5 Flare (model_openai-gpt-image-2-5-flare): width 1536, height 1024, quality high - Nano Banana 2.1 (model_google-gemini-nano-banana-2-1): aspect ratio 3:2, resolution 2K - Seedream 5.0 Pro (model_bytedance-seedream-5-0-pro): 2048 x 1360 Read each model's parameters with model_schema_get first; where a model offers only aspect presets, pick 3:2. Quote the cost with a dry run first and wait for my go. Launch the four with wait: false and collect them with one jobs_wait. Report each job's cost, wait and output size.Line them up and score
The agent can lay out the grid and fill the cost, wait and size columns from the jobs; the visual scores stay yours. A wordmark error eliminates a model however good the rest looks. In this run all four held the wordmark and light bar, so paint and light decided.
PromptDownload the four results, put them in one grid at the same size, and crop the front of each (light bar, wordmark, intake) at the same scale into a second grid. Write a scorecard with one column per model and these rows: wordmark spelled correctly, light bar, wheels and calipers, paint vs reference, light and mood vs brief, artifacts, cost, wait. Fill cost and wait from the jobs and leave the visual rows for me.A second seed for the top two
When two models are close, run each once more with the same inputs before you decide. Here Sunburst and Flare held the car again and the ranking did not change.
PromptRun GPT Image 2.5 Sunburst and GPT Image 2.5 Flare once more each, with exactly the same prompt, reference and settings. Show both new takes next to their first takes.File the test pack and report
Record the winner and runner-up with the date, and keep the inputs to rerun when a new model ships.
PromptCreate a collection called "Model test pack: product scenes". Add the studio reference and every take to it, and put the test prompt and the settings of each model in its description. Report every asset ID with its model, the cost and wait of each job, and the total cost spent.
Step by step in the web app (6 steps)Hide the steps
A shortlist from the ranking
Create › Images › View all models, with Input Image and Output Image ticked and the list ranked by Recommended. The run took the top two, GPT Image 2.5 Sunburst and Flare, and added Nano Banana 2.1 and Seedream 5.0 Pro; the input is the approved studio image of the car.
The product keep-list, then the scene
GPT Image 2.5 Sunburst, the studio image in Reference Images, Dimensions 1536x1024, Quality high, Image Count 1. Write the test prompt once: the product's keep-list, then the test scene.
PromptThe exact car from the reference image, with its body shape and proportions, liquid satin champagne paint, one continuous thin LED light bar across the full width of the nose, the spaced AURELLE wordmark in chrome capitals centered under the light bar, wide dark lower intake with fine horizontal slats, dark twisted multi-spoke turbine wheels with gold brake calipers, and black glass roof unchanged, parked on a gravel overlook on a high mountain pass at sunrise. Snow-capped peaks and a winding road behind, low warm sun from the left raking along the side of the car, cold blue shadows, thin mist in the valley below. Three-quarter front view at headlight height, the light bar lit and the AURELLE wordmark facing the camera and sharp. Soft contact shadow under the tires on the gravel. 3:2 landscape. No other cars, no people, no other text or logos. Style: automotive launch photography, controlled reflections, perfect panel gaps, no other brands.Change one thing: the model
Keep the prompt and reference and switch to GPT Image 2.5 Flare, then Seedream 5.0 Pro (2048 x 1360), then Nano Banana 2.1 (Aspect Ratio 3:2, Resolution 2K). Never tune the prompt per model, or you compare prompts, not models.
Same size, same crops
Line the four up at the same size and crop the front of each at the same scale. All four kept the wordmark and light bar, so paint and light decided: Nano Banana went cool and silvery, Seedream looked overcast and was the slowest.
A second seed for the top two
Sunburst and Flare were close, so each ran once more with the same inputs. Both held the car again and the ranking didn't change.
Winner and runner-up
Score wordmark, light bar, wheels and calipers, paint, light, artifacts and wait: Sunburst wins for its light, Flare is the runner-up for drafts. Write it in Settings › Project › Agent › Project Instructions, and keep the prompt and reference as a test pack to rerun when a new model ships.